Evolving GPU Kernels with LLMs
Why LLMs turn evolutionary program synthesis into a practical method for discovering fast GPU kernels, argued from convergence theory first principles.
By Jack Foxabbott, Founding Member of Technical Staff
Large language models turn evolutionary program synthesis from theory into practice. Here’s the argument from first principles.
In the previous post, we showed that diversity is the critical variable in evolutionary algorithms. Too little and the population collapses to a local optimum. Too much and it wanders randomly. Maintaining diversity helps the search explore alternatives instead of settling prematurely on one approach.
That was on a continuous function in . Now the individuals are not points on a heatmap but programs (specifically, GPU kernels) and the search space is the space of all valid code.
The diversity story carries over, and it matters more here: the search space is harder, evaluation is expensive, and most random changes to code are destructive.
GPU kernels are hard
Writing fast GPU kernels is one of the most demanding tasks in software engineering. Everything is coupled: tiling strategy, occupancy, register pressure, memory access patterns. A small change to one dimension can cause a performance cliff in another. What’s optimal on an H200 may be suboptimal on a B200.
The search space is combinatorial. For any given operation, you’re choosing among data types, input shapes, target devices, and an infinite space of algorithmic rewrites. Layer on multiple objectives (latency, memory usage, numerical accuracy) and you have a Pareto frontier, not a single answer.
This is exactly the kind of problem evolutionary algorithms are built for: huge, multi-modal search spaces where gradient information is unavailable. But there’s a catch.
Classical genetic programming breaks code
The traditional approach to evolving programs is genetic programming (GP): represent programs as syntax trees and apply random structural mutations: swap a subtree, change an operator, delete a node.
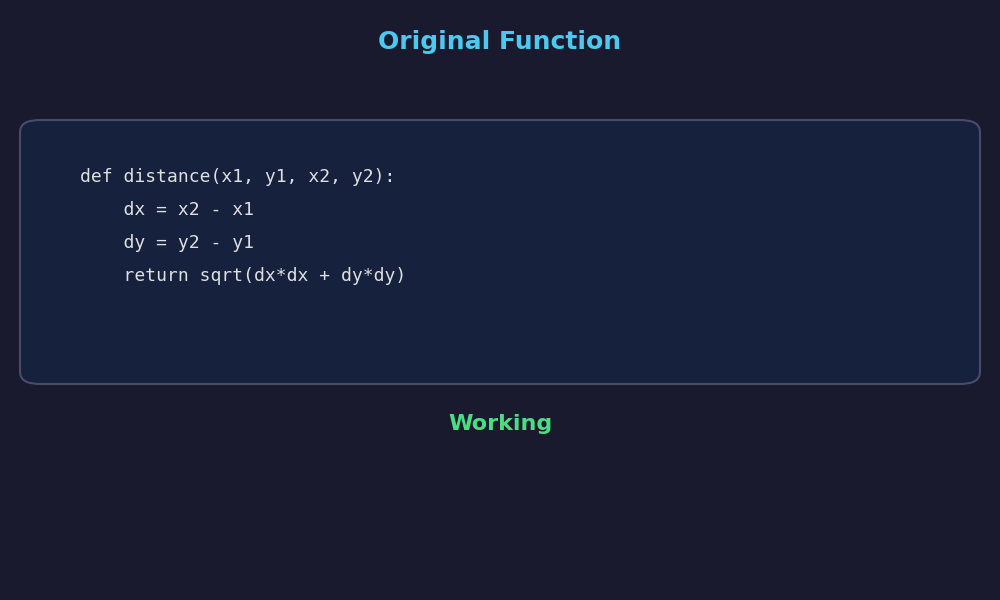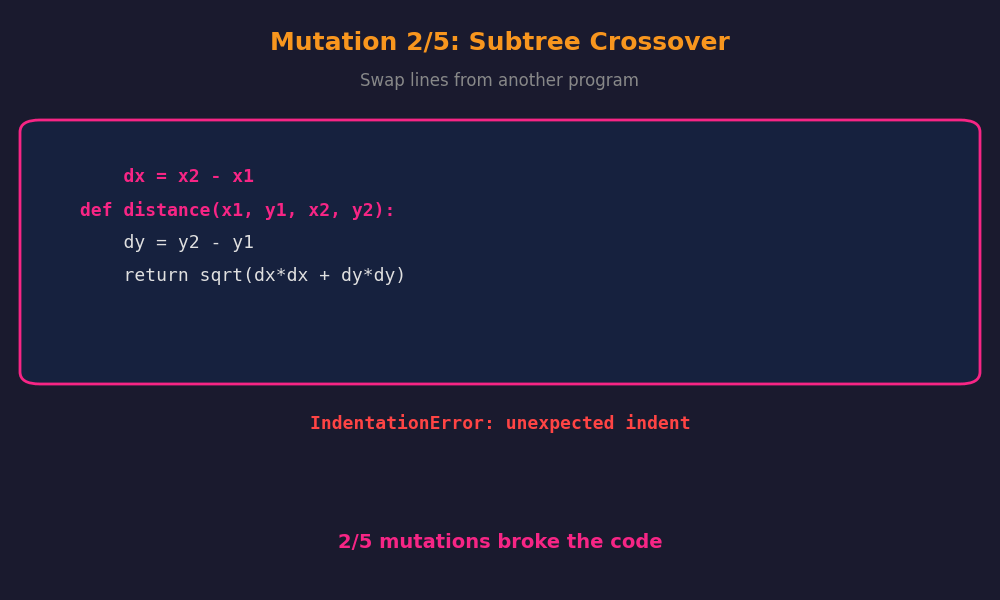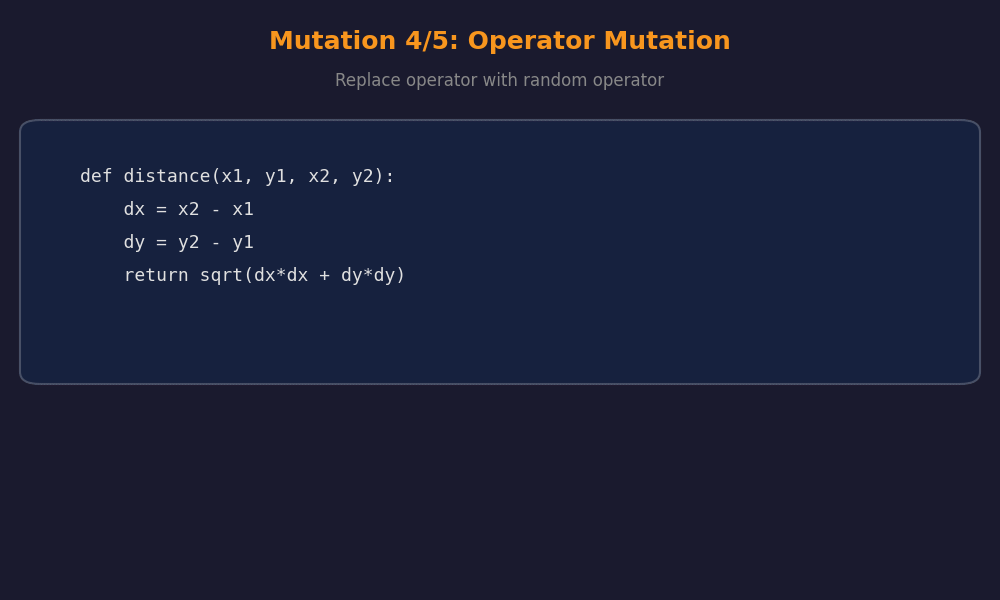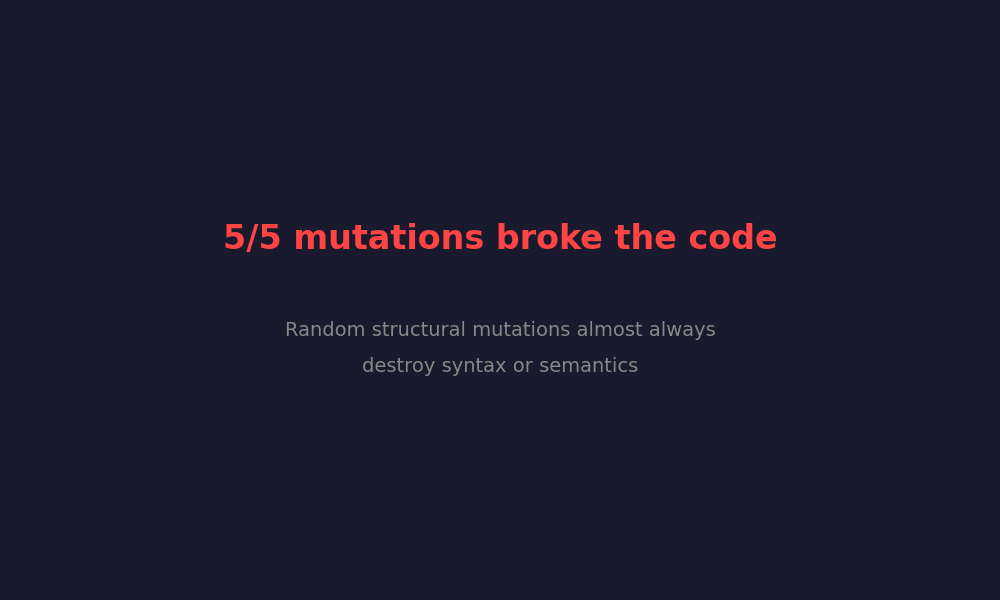
Random structural mutations almost always produce broken code. Take a function that computes Euclidean distance and apply five classical GP mutations:
def distance(x1, y1, x2, y2):
    dx = x2 - x1
    dy = y2 - y1
    return sqrt(dx*dx + dy*dy)
Table 1
5 out of 5 mutations break the code. This is the norm. Most of the search budget in classical GP goes to programs that don’t even parse, let alone produce correct results.
The practical challenge extends beyond ergodicity: random mutations can produce a wide range of programs, but useful candidates may be rare. Dang et al. (2016) analyzed how diversity mechanisms and crossover improve expected runtime on Jump benchmark functions.
LLMs as mutation operators
Large language models fix this. Instead of random structural perturbations, an LLM can:
- Understand code semantics, so mutations are meaningful, not random.
- Read documentation and hardware specs to guide changes toward known optimization strategies.
- Produce code that compiles and runs. Most LLM-generated mutations are syntactically valid.
- Control diversity directly via temperature. Low temperature produces conservative edits; high temperature produces radical rewrites.
This approach has become widespread. Lehman et al. (2022) introduced Evolution through Large Models (ELM), showing that LLMs trained on code can serve as mutation operators for genetic programming, generating hundreds of thousands of functional programs in a domain absent from training data. Meyerson et al. (2024) formalized why this works: LLM-based crossover implicitly builds a probabilistic model of parent genotypes and samples offspring, connecting it to Estimation of Distribution Algorithms (EDAs). The pre-trained distribution concentrates mass on syntactically valid, semantically coherent programs, so most mutations stay in a productive neighborhood.
Google DeepMind’s FunSearch (Romera-Paredes et al., 2024) applied this to mathematical discovery, pairing an LLM with an evaluator in an island-based evolutionary loop to find new constructions for the cap set problem. Its successor AlphaEvolve (Novikov et al., 2025) operates directly on code diffs and achieved a 23% speedup on a critical Gemini training kernel. Sakana AI’s ShinkaEvolve (Lange et al., 2025) pushed sample efficiency further, finding state-of-the-art circle packing solutions in roughly 150 evaluations using novelty rejection-sampling and bandit-based LLM ensemble selection.
In evolutionary terms, LLMs can provide structured diversity: variation in algorithmic choices informed by code patterns learned during training. The search tests whether those changes are useful through compilation, correctness checks and benchmarking.
Why kernels make the problem harder
Even with LLMs as the mutation operator, kernel optimization presents challenges that amplify the importance of diversity management:
- Compilation cost. Each candidate must compile, often with expensive autotuning. You can’t evaluate thousands of candidates cheaply.
- Hardware specificity. The optimal kernel for one GPU architecture may be suboptimal for another.
- Correctness validation. Fast but wrong is worthless. Every variant needs numerical verification against a reference implementation.
- Multiple objectives. Speed, memory, and numerical precision are all in tension.
- DSL complexity. GPU domain-specific languages (Triton, CuTe/CUTLASS, Helion) are niche and under-represented in LLM training data. Mutations need documentation-grounded guidance, not just pattern matching.
Every evaluation is expensive, which means every mutation must count. You can’t afford to waste budget on redundant or random candidates.
Applying the search principles
Consider what an LLM-based kernel evolution system looks like through the lens of Rudolph’s (1994) convergence result. He showed global convergence for specific finite-state genetic algorithms that retain the best solution found and allow mutation between any pair of bit strings.
Elitism is straightforward: always keep the best kernels across generations. Never discard a kernel that’s faster than everything else you’ve seen.
Ergodicity concerns which states a search process can reach. For kernel evolution, the practical question is how often a mutation produces a useful candidate. An LLM can propose code changes informed by patterns learned during training, while temperature changes the sampling distribution.
It helps to think about two competing clocks. The takeover clock measures how quickly selection fills the population with copies of the current best. This is pure exploitation, and it runs at a rate dictated by tournament size and population structure. The escape clock measures how quickly mutations can produce something genuinely different: a new algorithmic strategy, a gap-crossing move. LLMs speed up the escape clock dramatically, because meaningful mutations happen with practical probability, not astronomically small probability. But the takeover clock is unchanged. The design problem is ensuring escape stays ahead of takeover long enough to discover the right algorithmic basin.
And recall Dang et al.’s (2016, 2018) analyses: diversity and crossover can improve expected runtime on Jump benchmark functions under the algorithms and parameter settings studied. For kernel evolution, diversity means the population contains genuinely different algorithmic strategies (not just minor parameter variations of the same approach).
Controlling diversity in practice
Just as in the Rastrigin example from the previous post, diversity in an LLM-based evolutionary system is controlled by tuning multiple knobs:
Table 2
The general strategy mirrors the Rastrigin example: explore broadly early, exploit the best later. In early generations, high temperature, diverse planning prompts, and weak selection maximize the variety of kernel strategies explored. In later generations, tighter selection, lower temperature, and shared insights focus the population on refining the most promising approaches.
Temperature is particularly interesting because it maps directly onto the exploration/exploitation tradeoff that Dang et al. showed determines convergence speed. High temperature increases the effective mutation step size, helping the population explore diverse algorithmic strategies and escape local optima. Low temperature keeps mutations conservative, refining solutions that already work. This is the continuous-code analog of the adaptive mutation schedule () we used on the Rastrigin function.
Insight sharing plays the role of crossover. When one agent’s successful strategy informs another agent’s mutations, the LLM is recombining partial solutions from different parents. Dang et al. (2016, 2018) analyzed how population diversity makes crossover effective on Jump benchmark functions. If all agents have converged to variations of the same tiling strategy, sharing between them may offer little additional variation. Diverse planning prompts are what create the variation that makes insight sharing productive in the first place.
One open problem: measuring diversity of kernels is not well-defined. For points in , you compute pairwise distances. For kernel code, there’s no consensus. AST distance? Algorithmic similarity? Performance profile distance? Without a good diversity metric, you can’t adaptively control diversity the way Doerr, Giessen, and Witt (2019) showed is optimal for simpler search spaces. This remains an active research question.
What the literature shows
The empirical results from LLM-based evolutionary systems are striking. AlphaEvolve discovered a 4x4 complex matrix multiplication algorithm using 48 scalar multiplications, improving on Strassen (1969), and sped up a critical Gemini training kernel by 23%. FunSearch found new constructions for the cap set problem (the largest improvement on the asymptotic lower bound in 20 years). KernelBench (Ouyang et al., 2025) established that LLMs can generate correct CUDA kernels, though optimality remains challenging for single-shot generation, exactly the gap that evolutionary iteration fills.
These results share a pattern: the LLM alone isn’t enough. Single-shot prompting produces reasonable but rarely optimal code. It’s the evolutionary loop (iterative mutation, selection, and diversity management) that pushes performance past what any single LLM call achieves. The LLM provides structured diversity; the evolutionary algorithm provides the search discipline to use it well.
What we’re doing
At Geometric, we use these ideas to evolve GPU kernels. We’ll have more to say about our system and results in a future post.
The practical lesson from the previous post carries through: whether the individuals are points in or GPU kernels in CuTe DSL, controlling diversity is the key to efficient evolutionary search. LLMs propose code variations, and temperature helps adjust the range of candidates explored. Evaluation determines which changes improve the kernel.
References
- G. Rudolph. Convergence Analysis of Canonical Genetic Algorithms. IEEE Transactions on Neural Networks, 5(1):96–101, 1994. doi:10.1109/72.265964
- D.-C. Dang, T. Friedrich, M. Kötzing, M.S. Krejca, P.K. Lehre, P.S. Oliveto, D. Sudholt, A.M. Sutton. Escaping Local Optima with Diversity Mechanisms and Crossover. GECCO 2016, pp. 645–652. doi:10.1145/2908812.2908956
- D.-C. Dang et al. Escaping Local Optima using Crossover with Emergent Diversity. IEEE Transactions on Evolutionary Computation, 22(3):484–497, 2018. doi:10.1109/TEVC.2017.2724201
- J. Lehman, J. Gordon, S. Jain, K. Ndousse, C. Yeh, K.O. Stanley. Evolution through Large Models. arXiv:2206.08896, 2022.
- E. Meyerson, M.J. Nelson, H. Bradley, A. Gaier, A. Moradi, A.K. Hoover, J. Lehman. Language Model Crossover: Variation through Few-Shot Prompting. ACM Transactions on Evolutionary Learning and Optimization, 2024. arXiv:2302.12170
- B. Romera-Paredes et al. Mathematical Discoveries from Program Search with Large Language Models. Nature, 625:468–475, 2024.
- A. Novikov et al. AlphaEvolve: A Coding Agent for Scientific and Algorithmic Discovery. arXiv:2506.13131, 2025.
- J.R. Koza. Genetic Programming: On the Programming of Computers by Means of Natural Selection. MIT Press, 1992.
- A. Ouyang et al. KernelBench: Can LLMs Write Efficient GPU Kernels? ICML 2025. arXiv:2502.10517
- B. Doerr, C. Giessen, C. Witt. The (1+λ) Evolutionary Algorithm with Self-Adjusting Mutation Rate. Algorithmica, 81:593–631, 2019. doi:10.1007/s00453-018-0502-x
- R.T. Lange, Y. Imajuku, E. Cetin. ShinkaEvolve: Towards Open-Ended and Sample-Efficient Program Evolution. arXiv:2509.19349, 2025.